7 Data Catalogue Examples for Better Governance
|
0
min read

A catalog is only useful when people trust it. The popular advice says to treat a data catalogue example as a searchable inventory, but that misses the test that matters. The strongest catalog depends on what metadata it captures, how ownership and lineage are enforced, how assets are organized, and whether each record carries enough reliability signal for teams to act on it confidently. That's why the best examples look different depending on the operating model, from governance-heavy platforms to active metadata systems, from open-source flexibility to privacy-first observability inside your own environment.
That lens matters because modern catalogs evolved from narrow schema lists into governance systems. Early catalog roots go back to data dictionaries and manual metadata stores, while newer platforms support lineage, review workflows, and trust across large estates, as summarized in the evolution of catalog history and adoption patterns in enterprise data governance DataGalaxy's history of the data catalog and StatPit's 2026 adoption summary. For teams looking for a data catalogue example, the key question isn't whether a tool can list tables. It's whether the catalog helps people discover, validate, classify, and use data with less friction.
That's where dignity-style observability belongs in the comparison, because digna combines catalog-style discovery with anomaly detection, timeliness, validation, and schema tracking inside the customer environment. The seven patterns below show how different catalog designs work, where they fit, and what trade-offs teams should expect.
Table of Contents
1. digna
digna fits the privacy-first data catalogue example pattern because it treats metadata as part of operational reliability, not only discovery. The platform runs inside your own cloud, VPC, or data center, so production data stays in your environment and checks run in-database, which reduces movement and aligns with security controls. That makes it a practical option for teams that need catalog visibility plus observability evidence they can trust in regulated settings.

Reliability context matters more than a static inventory
digna's strength comes from putting anomaly detection, timeliness tracking, record-level validation, and schema change monitoring into one UI. AWS separates metadata management, catalog, and governance, with the catalog supporting discovery and governance defining usage policy AWS metadata management guidance. digna sits closer to the operational edge, where teams need to see whether data arrived on time, whether a schema shifted, or whether a business rule failed before a dashboard or model breaks.
The platform fits finance, healthcare, telecom, and public sector teams that need traceability and compliance-ready evidence. It also includes a scheduler, catalog, integrations, and collaboration features from the start, so the catalog record and the monitoring workflow stay connected instead of drifting into separate tools. For teams comparing catalog models, that combination matters because it ties governance to day-to-day reliability checks rather than leaving quality signals in another system. Its data observability approach shows the pattern clearly.
Practical rule: If your team spends more time explaining why data is wrong than finding it, observability-linked metadata will usually outperform a pure inventory.
digna also helps mixed technical groups work from the same system, including engineers, analysts, governance leads, and business users. The trade-off is deployment ownership, since the organization has to manage the environment itself. For teams that can support that model, the result is a catalog pattern built around trust and operational evidence.
Website: digna.ai
2. Alation Data Catalog
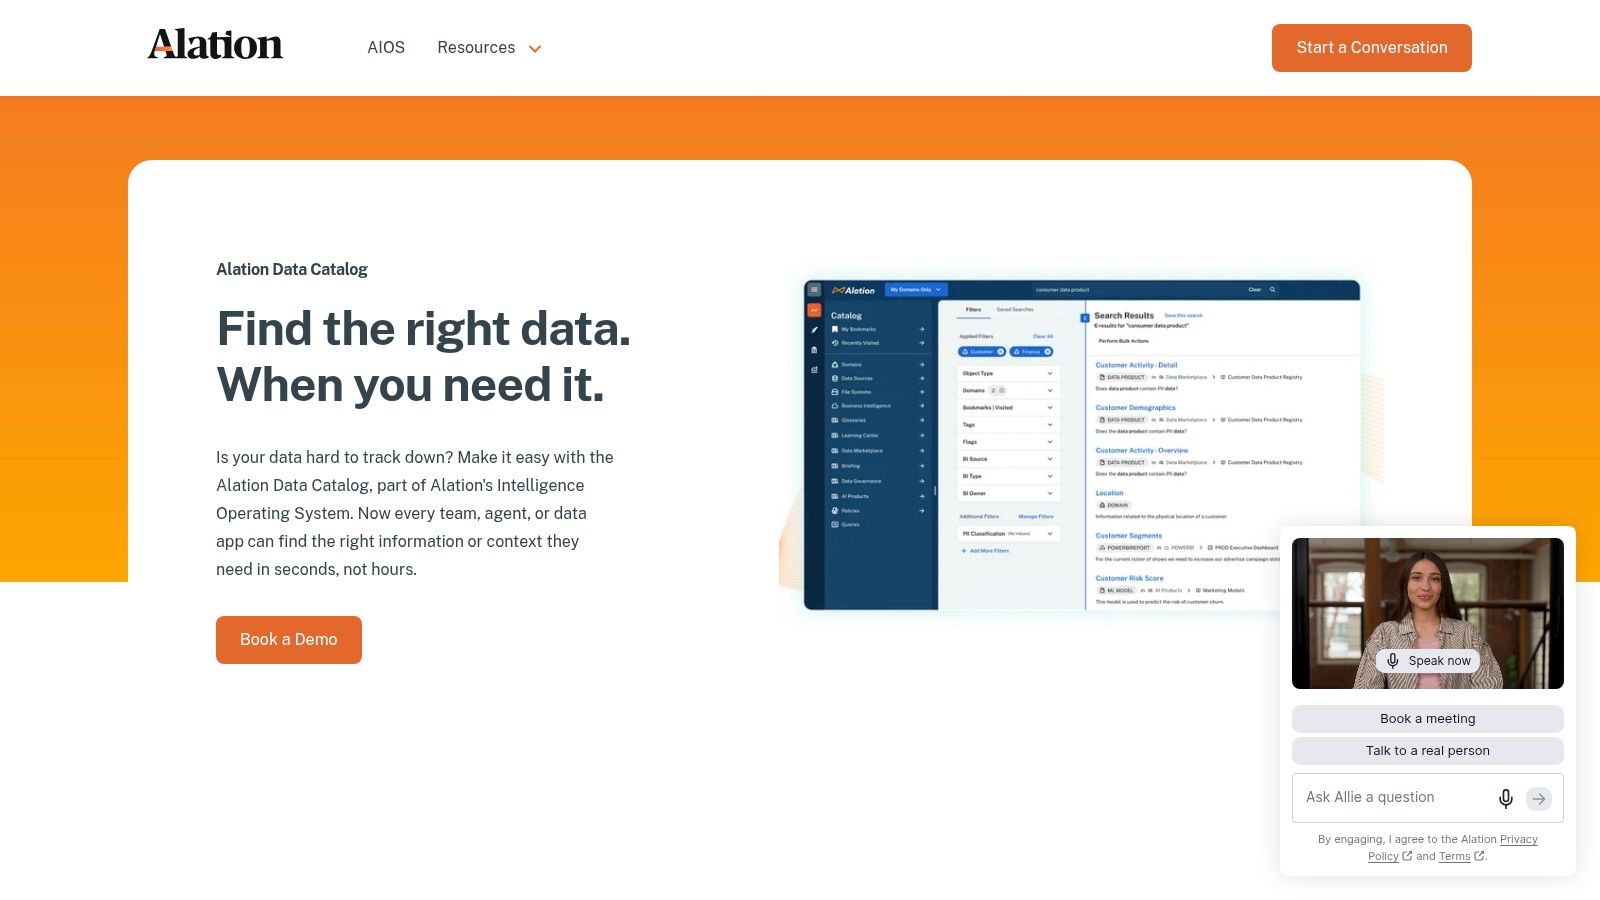
A search-led catalog only works when users trust what search returns. Alation is the clearest example of that pattern. It serves large enterprises that need discovery, lineage, and broad connector coverage, but the true test is whether business users can start with a question and still land on governed content.
Strong search depends on stewardship discipline
The value comes from more than indexing. Glossary terms, policy context, lineage, and usage signals have to be maintained well enough that search results do not become a pile of attractive but untrusted assets. Alation's product page highlights natural-language search, end-to-end lineage, 120+ prebuilt connectors, and an open connector framework. That mix makes sense where stewardship is federated across many systems and glossary ownership is explicit.
That condition matters. If an organization has many sources but no certification rules, popularity-ranked search can surface content faster without improving trust. In that case, discovery outpaces governance, and users still need manual validation.
The pattern works best when adoption is the bottleneck and metadata discipline already exists. Business users get a familiar search experience, while data teams keep a governed structure across a fragmented estate. The trade-off is operational effort. Broad coverage usually means more enablement work, especially when ownership and business definitions are still inconsistent.
For a data catalogue example, Alation shows how governed discovery can feel natural without becoming lightweight. The catalog is strongest when search, stewardship, and certification are already connected. It is weaker when the organization still needs to define who owns assets, which ones are trusted, and how terms should be used. Related reading: How digna defines a data catalog in practice
Website: Alation Data Catalog
3. Collibra Data Catalog
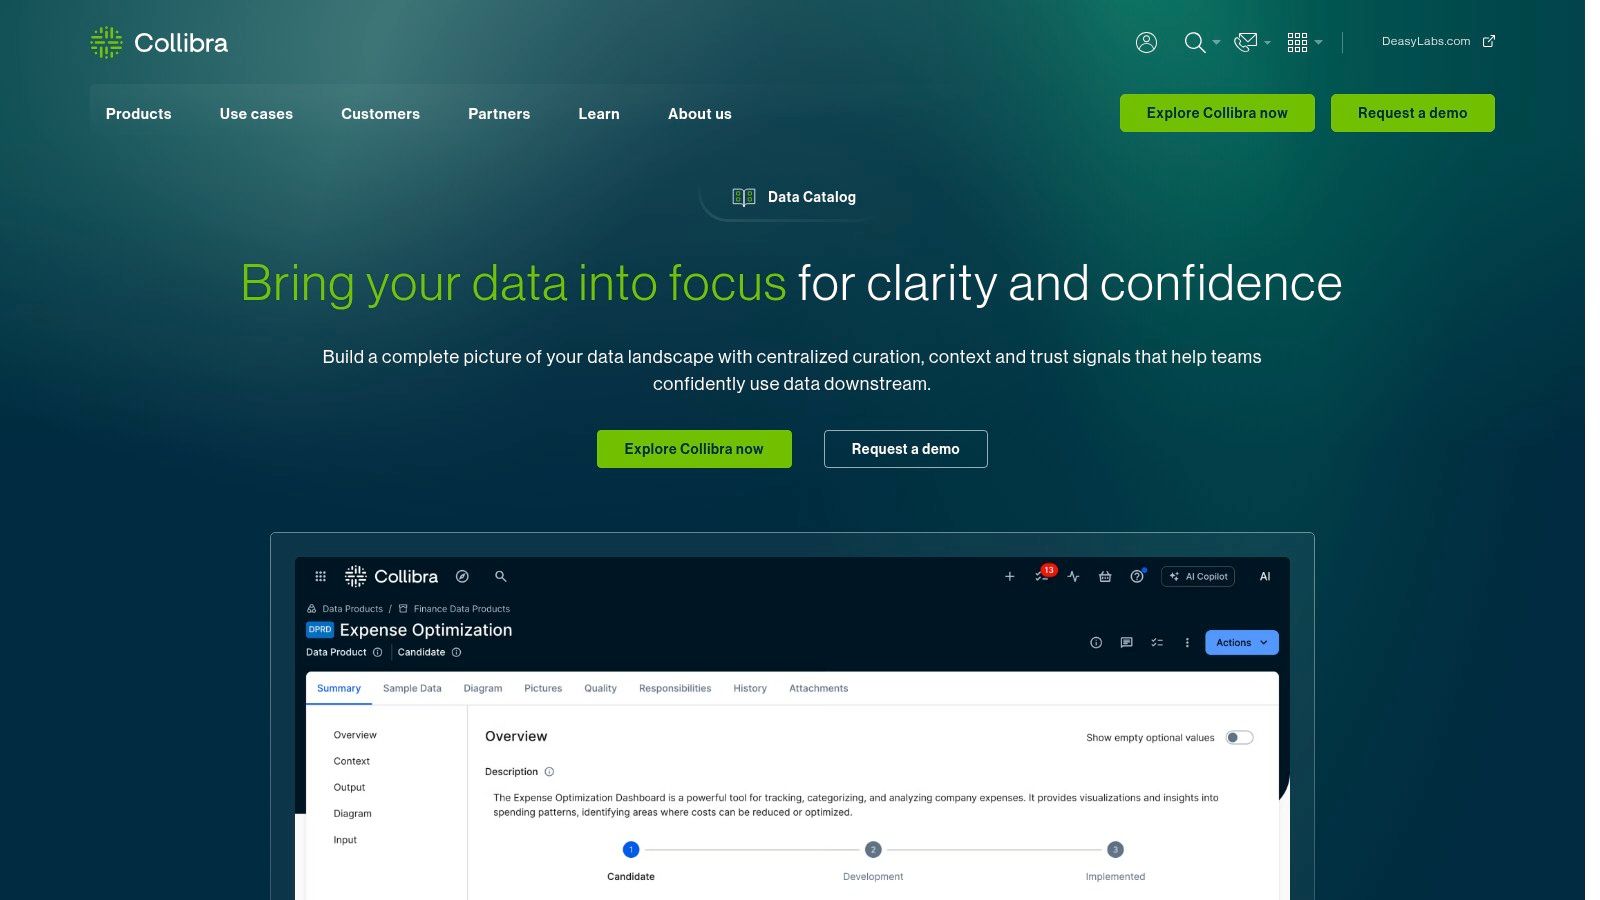
Collibra fits the enterprise governance pattern. It is built for organizations that need discovery, lineage, sensitive-data classification, and policy-driven workflows to operate inside a broader data intelligence model. That matters when legal, risk, compliance, and the data office all need to review the same asset record.
Governance depth pays off in complex operating models
The practical advantage is control. Collibra's product page points to a centralized inventory, more than 100 native integrations, automated curation, sensitive-data labeling, interactive lineage, and a marketplace-style access workflow. That combination works when the catalog must show what an asset is, who approved it, which policy applies, and how access is governed.
The pattern is practical when legal, risk, and compliance must co-approve assets, and when sensitive-data labeling is mandatory. It is also a fit for organizations with multiple stewardship layers and formal review paths. It is less practical when the org has fewer than 3 stewardship layers and needs lightweight discovery. In that setting, the operating overhead can outrun the value of the extra control.
Collibra also suits teams that are turning data products into governed reuse. Marketplace-style access and glossary context help package trusted data, but only if ownership and review responsibilities are already clear. The trade-off is obvious. The richer the control model, the more discipline teams need around roles, administration, and exception handling.
A governance-first catalog should surface policy at the point of discovery, so users see the rule before they request the asset.
How digna defines a data governance strategy gives a useful reference point here. Collibra makes that strategy operational through the catalog layer. For organizations that need traceability, sensitive-data handling, and shared accountability, that is the value of the pattern.
Website: Collibra Data Catalog
4. Atlan Active Metadata Catalog
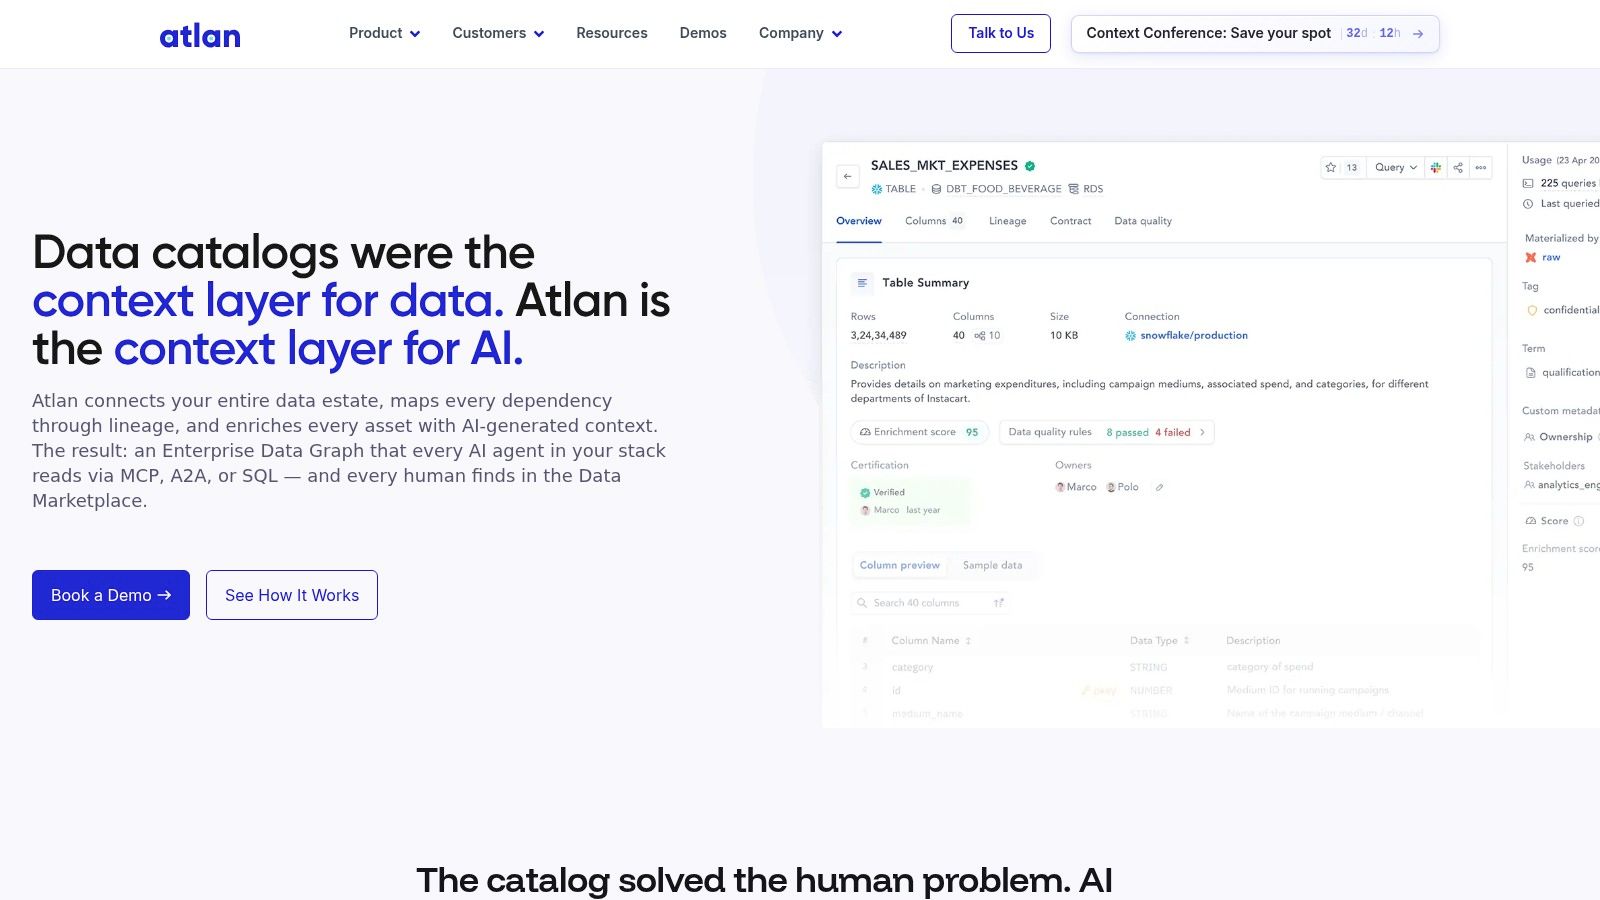
Atlan fits the active metadata pattern. The catalog is designed for teams that want metadata to change as data changes, so freshness, lineage, certification, and domain context stay visible in the workflow. That makes it useful for analytics groups and data mesh programs where ownership shifts quickly and manual upkeep falls behind.
Active metadata works when the operating model is already explicit
Atlan's data discovery catalog page points to natural-language search, automated lineage, active-metadata automations, and AI-assisted documentation. Those features matter most when the catalog needs to reflect live operational context, not a one-time documentation pass. If ownership, freshness, and certification change often, a static catalog becomes stale quickly.
The pattern works when domain boundaries are defined, ownership contracts exist in code, and metadata pipelines are event-driven. In that setting, the catalog can update context as changes happen and keep stewardship distributed. Without those conditions, automation can scale confusion just as easily as it scales documentation.
When it works: domain teams already own data products, metadata events are reliable, and the catalog can publish updates without manual intervention. When it fails: boundaries are vague, ownership lives in spreadsheets, and stale signals overwrite local context.
An analyst note from digna on data discovery fits here. Discovery only becomes usable when the catalog reflects how teams already work. Atlan is strongest where collaboration speed matters and the organization wants a modern interface that encourages participation, but the trade-off is clear, it depends on disciplined domain design before automation can help.
Website: Atlan Data Discovery Catalog
5. Microsoft Purview Unified Catalog
Microsoft Purview fits the cloud-native stewardship pattern, but only under the right operating conditions. It is most practical when a Microsoft-heavy estate already spans Azure, Fabric, and OneLake, and the team needs governance to expand in stages rather than through a full replatforming. In that setup, the catalog follows the platform the organization already runs.
Usage-based governance fits incremental rollouts
Purview's Unified Catalog documentation shows a model built around multicloud scanning, central data maps, lineage, classifications, and DGPU-based governance processing. The practical value is not broad catalog theory. It is the ability to start with a limited scope, validate connectors, and expand governance where usage justifies the spend.
Choose this pattern when you need pay-as-you-go governance and Fabric integration without replatforming. Budget 2 to 3 sprints for connector validation on non-Microsoft sources, because coverage varies by connector and that affects adoption. The model is practical when roughly 70% or more of assets sit in Azure, Fabric, or OneLake, and less practical when the estate is multi-cloud with a thin Microsoft footprint.
That makes the trade-off clear. Microsoft-centered teams get tighter fit, lower integration friction, and a governance layer that sits close to the security stack they already use. Teams with mixed-source estates may still use Purview, but connector variance can leave important assets outside the catalog's most reliable coverage.
For a data catalogue example in a Microsoft-heavy estate, this is a reusable pattern rather than a generic catalog. It works best when governance maturity can grow in phases and the organization wants the catalog to follow its Microsoft operating model.
Website: Microsoft Purview documentation
Related reading: digna on metadata management
6. DataHub Open Source and DataHub Cloud
DataHub is the engineering-led flexibility pattern. It fits teams that want lineage, search, governance workflows, and observability signals without committing to a closed catalog stack. The open-source edition gives technical teams control. DataHub Cloud keeps the same model but removes much of the infrastructure burden.
Engineering control versus operational burden: what the open-source contract really costs
The strength of DataHub is not generic catalog breadth. It is the ability to shape metadata as part of the platform, not just consume it as a front-end tool. That makes the pattern practical for teams that already run internal platforms, custom connectors, and metadata pipelines they can maintain as the stack changes.
DataHub Cloud lowers the operational load, but the trade-off does not disappear. Open-source control still asks for upgrade management, connector upkeep, and someone who can keep ingestion healthy when upstream systems change. It fits when a platform team can own that work, and it becomes harder to justify when the organization lacks dedicated SRE or catalog operations capacity.
Fit signal | Practical if | Less practical if |
|---|---|---|
Operating model | engineering owns metadata workflows | the catalog is expected to run with little hands-on support |
Deployment choice | custom extensions and self-hosting matter | the team wants minimal infrastructure responsibility |
Reliability focus | ingestion pipelines are monitored and maintained | upgrades and connectors are left to ad hoc effort |
For buyers comparing a data catalogue example across deployment styles, DataHub is the clearest case of self-hosted control alongside a managed option. It works best when metadata infrastructure is treated like software, with ownership, release discipline, and clear operational accountability.
Website: DataHub
7. Informatica Cloud Data Governance and Catalog
For hybrid estates where scanner breadth determines whether the catalog is complete, Informatica prioritizes coverage over a lighter discovery experience. It suits organizations that already rely on Informatica tooling and need cataloging to connect with integration, quality, and governance work.
Breadth matters when the estate is messy
The catalog's product page highlights automated scanning, profiling, lineage, glossary, policy management, and adjacent data quality and integration services. That profile matters where cloud and on-prem systems both need to be covered, and where governance artifacts have to stay aligned with technical metadata. The value lies in full metadata coverage rather than lightweight discovery.
This pattern fits enterprises that need wide scanner support and tighter coupling to an existing data management stack. The trade-off is operational weight. Scope, administration, and enablement can become significant, especially when technical teams and governance users both depend on the same catalog. Adoption tends to be stronger when catalog work sits inside a broader operating model, not as a standalone search tool.
Choose Informatica when the estate requires broad scanner coverage and IDMC-linked quality or integration services. Choose Collibra when marketplace-style governance and business-user workflows matter more than scan depth. For readers comparing a data catalogue example with maximum platform breadth, Informatica is the clearest fit for organizations that want cataloging to function as part of a larger data management program.
Website: Informatica Cloud Data Governance and Catalog
Top 7 Data Catalog Comparison
Product | Implementation Complexity (🔄) | Resource & Ops (⚡) | Expected Outcomes (⭐📊) | Ideal Use Cases | Key Advantages (💡) |
|---|---|---|---|---|---|
digna | Medium (🔄🔄), in‑env install and module setup | Moderate‑High ⚡, customer manages infra; in‑database compute reduces data movement | High ⭐⭐⭐⭐, enterprise-grade observability, rapid TTV (insights <2 hrs) | Regulated enterprises needing privacy-first, in‑place checks | In‑environment execution, in‑database checks, modular licensing, AI anomaly + deterministic validation |
Alation Data Catalog | Medium‑High (🔄🔄🔄), governance and adoption work | Moderate ⚡, connectors + enablement for broad estates | High ⭐⭐⭐⭐, strong discovery, search and governance adoption | Large enterprises seeking governed data discovery and search | Natural‑language search, lineage, 120+ connectors, governance workflows |
Collibra Data Catalog | High (🔄🔄🔄), org‑level role/model setup required | High ⚡, significant enablement and operating‑model effort | High ⭐⭐⭐⭐, comprehensive governance, sensitive‑data controls | Complex orgs with compliance and data‑product needs | Centralized governance, sensitive‑data labeling, AI Copilot, marketplace/workflows |
Atlan, Active Metadata Catalog | Medium (🔄🔄), quicker UX but requires domain design | Moderate ⚡, modern UX lowers friction; some setup for domains | Good ⭐⭐⭐, faster adoption and collaborative metadata management | Data mesh/domain teams, collaboration‑focused analytics teams | Active metadata automations, AI‑assisted docs, domain/product workflows |
Microsoft Purview, Unified Catalog | Low‑Medium (🔄🔄), cloud‑native, incremental rollout | Moderate ⚡, pay‑as‑you‑go (DGPU) billing; connector variance | Good ⭐⭐⭐, unified catalog for Microsoft ecosystems | Microsoft/Azure/Fabric‑centric organizations | Multicloud scanning, Fabric/OneLake integration, transparent usage pricing |
DataHub (open‑source) / DataHub Cloud | Medium (🔄🔄), OSS requires engineering; Cloud eases ops | Variable ⚡, self‑host high; DataHub Cloud lowers operational load | Good ⭐⭐⭐, developer‑friendly metadata, strong lineage/search | Teams wanting OSS flexibility or a managed SaaS path | Open‑source community, flexible deployment, transparent starter pricing (Cloud) |
Informatica, Cloud Data Governance & Catalog (IDMC) | High (🔄🔄🔄), enterprise‑scale deployment and governance | High ⚡, broad scanners and ongoing administration | High ⭐⭐⭐⭐, deep scanning, profiling and enterprise integrations | Very large, hybrid estates needing extensive source coverage | Enterprise scanner breadth, detailed lineage, integrates with IDMC ecosystem |
Choose the Pattern Your Operating Model Can Sustain
The right catalog depends less on feature count and more on whether your operating model can sustain the behavior the tool expects. If you need enterprise governance and compliance evidence, Collibra or Informatica make sense. If adoption depends on fast, intuitive search, Alation is the sharper fit. If your teams work in domains and products, Atlan gives active metadata a practical home. If your estate is Microsoft-centered, Purview fits naturally. If engineering wants control and flexibility, DataHub is the open path. If reliability, privacy, and in-environment execution matter most, digna is the most operationally grounded pattern.
A useful way to compare them is to ask six questions. Can people find the asset quickly. Can they see lineage they trust. Can the glossary or taxonomy keep terms consistent. Can observability or freshness signals warn them before they use stale data. Can the deployment model match your security posture. And can your team afford the operating burden that comes with the chosen design?
Discovery: Alation and Atlan lead on search-led discovery, while Collibra, Purview, DataHub, Informatica, and digna pair discovery with different layers of governance or reliability.
Lineage: Collibra, Purview, DataHub, Informatica, and Alation emphasize lineage visibility, while digna ties reliability checks to schema and timeliness signals.
Taxonomy or glossary support: Collibra, Alation, DataHub, and Informatica push the strongest glossary and policy context, with Atlan and Purview leaning into operational context.
Observability context: digna is the most explicit fit, while DataHub and Collibra bring supporting signals into the catalog layer.
Deployment model: Purview and Cloud vendors favor managed or cloud-native paths, DataHub offers self-host or cloud, and digna runs inside customer infrastructure.
Operating burden: Open-source flexibility and enterprise governance depth both demand ownership. The difference is where the burden sits, in engineering, administration, or both.
The practical sequence is simple. Define the metadata record first, choose ownership and taxonomy rules second, pilot one high-value dataset third, attach trust signals such as lineage, freshness, or validation next, and then measure whether users can find the asset and confidently use it. A catalog earns adoption when it helps people make decisions faster with fewer arguments about what the data means.
digna gives teams a different kind of catalog experience, one where discovery and observability stay connected inside the same environment. If you need a platform that ties metadata to anomalies, timeliness, validation, and schema changes without moving production data out of your control, visit digna and evaluate whether that operating model fits your data catalogue example better than a static inventory ever could.


